Apache Iceberg Partitioning: How to Choose a Design That Survives Production
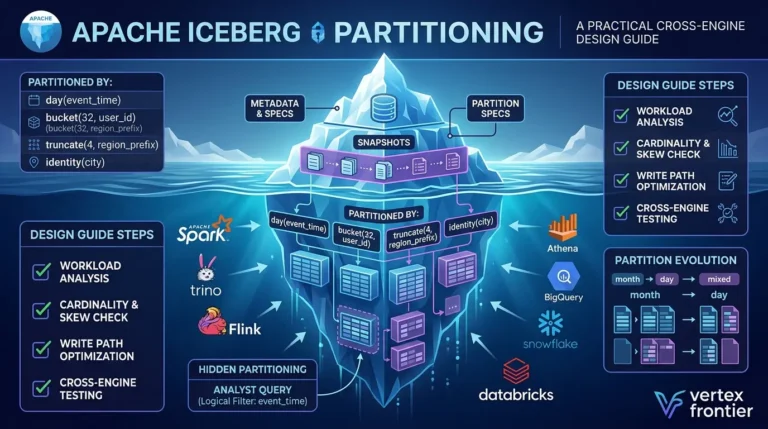
Learn Iceberg Partitioning best practices: choose the right transforms, avoid small files and data skew, evolve partition specs, and validate designs across major engines.
Learn Iceberg Partitioning best practices: choose the right transforms, avoid small files and data skew, evolve partition specs, and validate designs across major engines.
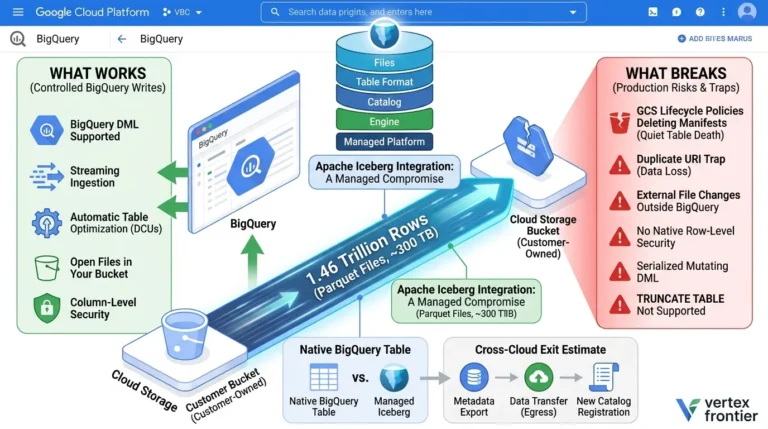
A verified field guide to Apache Iceberg on BigQuery: current limits, data-loss traps, costs, migration checks, and cross-engine design.
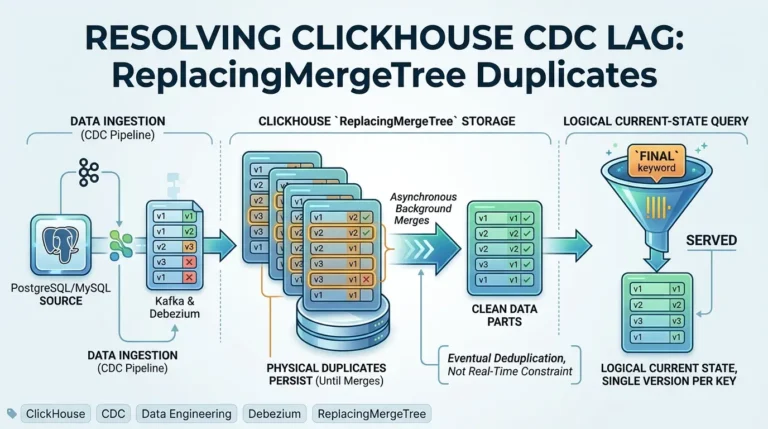
Learn why ClickHouse ReplacingMergeTree duplicates persist, how CDC ordering and tombstones cause lag, and how to fix them safely in production.
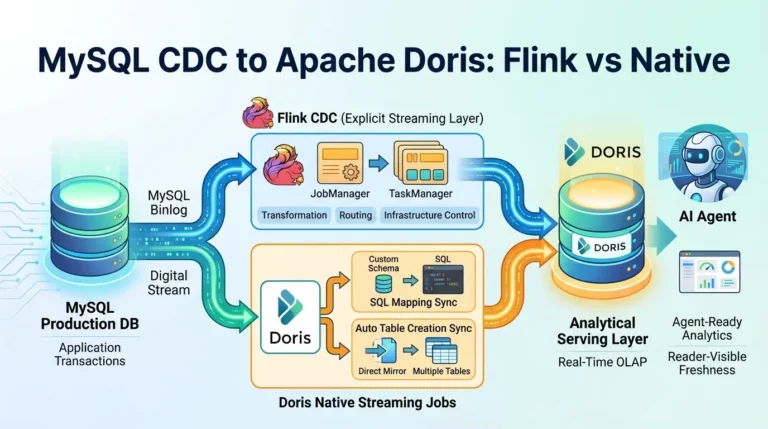
Learn how to sync MySQL CDC to Apache Doris with Flink or native Streaming Jobs, handle deletes and schema changes, and measure freshness safely.
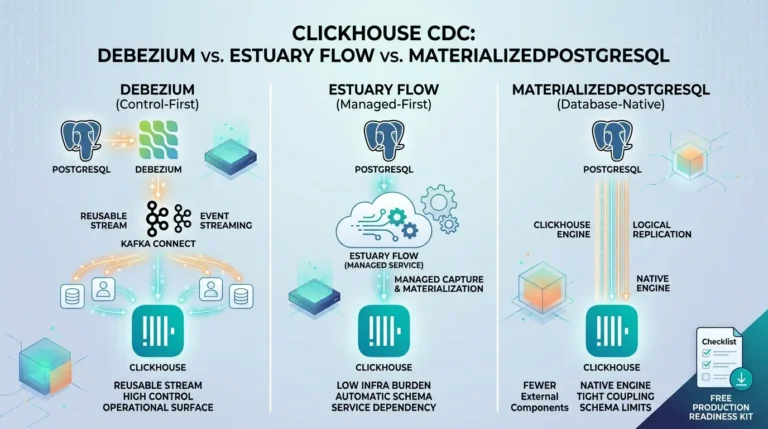
Debezium vs. Estuary Flow vs. MaterializedPostgreSQL for ClickHouse CDC. See trade-offs in Kafka, correctness, schema, recovery, cost, and scale.
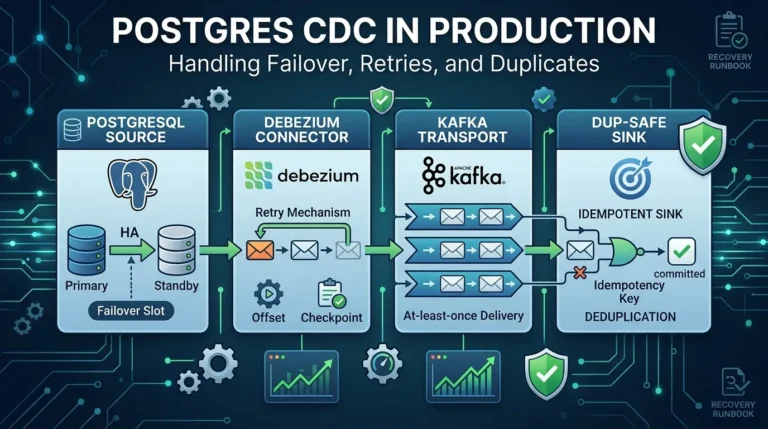
Production-tested guide to Postgres CDC: How to architect resilient pipelines, handle WAL failovers, eliminate duplicates, and configure retries properly.
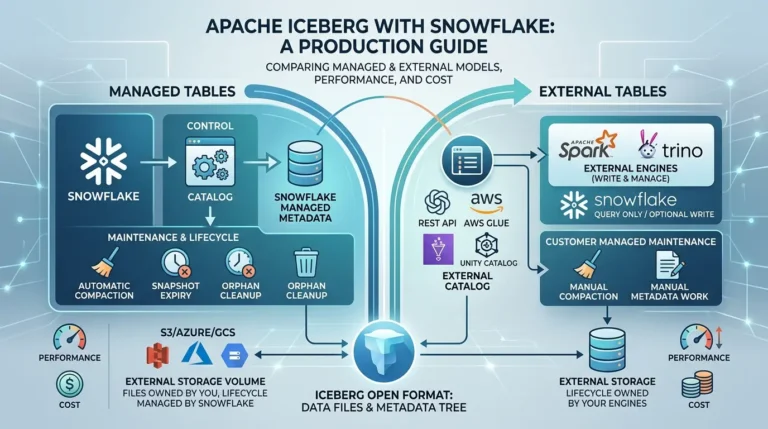
Apache Iceberg with Snowflake: A Production Guide
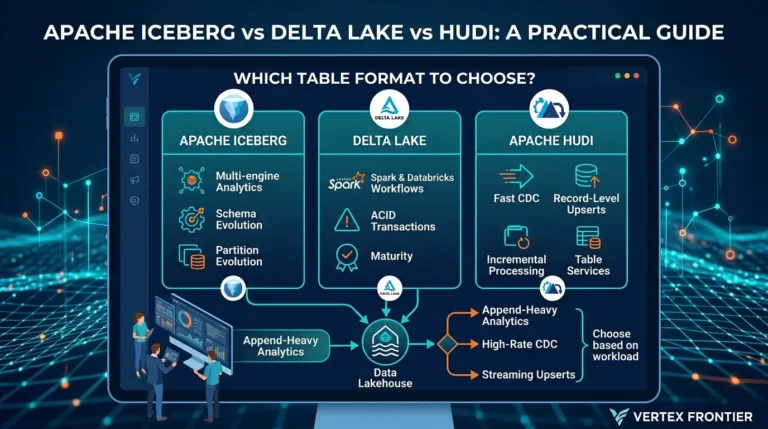
Apache Iceberg vs Delta Lake vs Hudi compared by workload, CDC, engines, maintenance, migration, and cost so you can choose a table format confidently.

Learn how to migrate from Parquet to Apache Iceberg with a preflight checklist, procedure matrix, validation protocol, cutover plan, and rollback controls.

Is Parquet enough or do you need Apache Iceberg? Compare file format vs table format, ACID compliance, partition evolution, and real-world performance.