
A vector database can be perfectly authenticated and still leak the wrong document.
That is the security problem most comparison articles miss.
An API key may prove that a request came from an approved service. RBAC may restrict that service to a collection or project. TLS may protect the request while it travels across the network. None of those controls, by itself, proves that the retrieved chunk belongs to the user who asked the question.
For a production RAG system, vector database security is a stack. It includes identity, authorization, network exposure, encryption, tenant isolation, metadata handling, audit evidence, backups, deletion, patching, and the application logic that connects a person to a retrieval result.
This guide compares that stack across Pinecone, Qdrant, Weaviate, and pgvector/PostgreSQL. It focuses on the controls that change depending on deployment model, the defaults that can surprise engineers, and the tests that should pass before a vector store is trusted with sensitive data.
Product controls, plan gates, cloud regions, defaults, release behavior, and security advisories change. Treat the official documentation linked in each section as the authority for the exact version, edition, region, and deployment you operate. This article provides a hardening framework and verification protocol; it is not a guarantee that any product is secure by itself.
The central rule: database authorization controls what a caller can do to a database. Retrieval authorization controls which documents that caller is allowed to see. A secure RAG system needs both.
Key takeaways
Click any topic to expand or collapseDeployment Models & Control
Do not compare these products without naming the deployment model. Pinecone managed, Qdrant self-hosted, Weaviate Cloud, and pgvector on PostgreSQL place different controls on different teams.
Qdrant Self-Hosted Risks
Qdrant self-hosted requires perimeter hardening before it is connected to a network. The official documentation describes open binding, no authentication, and no TLS as default risks in self-hosted deployments.
Pinecone Private Endpoints
Pinecone Private Endpoints protect documented data-plane traffic; they do not make the control plane private.
Weaviate Authentication & RBAC
Weaviate authentication and RBAC are useful only when anonymous access, bootstrap behavior, TLS paths, and version boundaries are tested on the actual release.
pgvector Security Model
pgvector does not add a separate security model. Its security is PostgreSQL security: roles, grants, TLS, pg_hba.conf, RLS, logging, backups, and extension patching.
Authorization Boundaries
Namespaces, collections, tenant shards, metadata filters, and RLS are not automatically complete document-level authorization boundaries.
What is vector database security?
Vector database security is the set of controls that protects embeddings, source documents, metadata, indexes, queries, credentials, backups, and generated context from unauthorized access, modification, disclosure, or deletion.
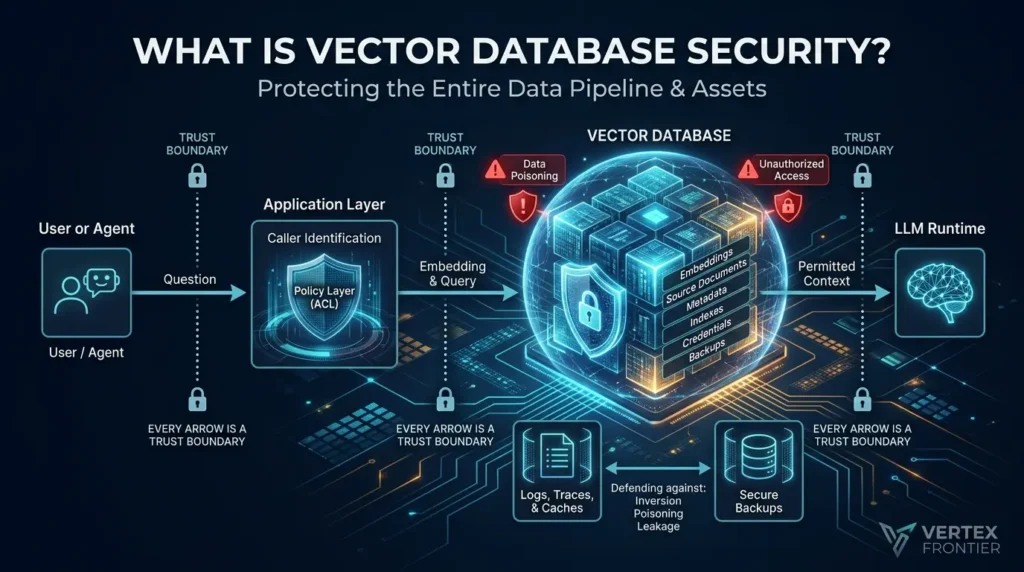
That definition is intentionally wider than “database authentication.” A vector store sits inside a pipeline that usually looks like this:
- A user or agent submits a question.
- The application identifies the caller.
- A policy layer decides which sources the caller may access.
- The application creates an embedding and queries the vector store.
- The store returns candidate chunks.
- The application passes permitted context to an LLM.
- Logs, traces, caches, backups, and evaluation systems may retain parts of the exchange.
Every arrow is a trust boundary.
The OWASP GenAI risk guidance on vector and embedding weaknesses treats risks such as unauthorized retrieval, cross-context leakage, embedding inversion, and data poisoning as part of the broader AI security problem. That does not mean every embedding can be reversed into readable source text. It means the model, data, access path, and attacker capability must be included in the threat model.
Vertex Frontier’s existing guides on enterprise RAG security and ACL architecture and document-level access control in RAG cover the application authorization problem. This article adds the product and deployment layer: what the database exposes, what it logs, and where responsibility moves when you choose managed, self-hosted, or PostgreSQL-based infrastructure.
A vector database is not just an index. It is a sensitive data system connected to identity, policy, infrastructure, and an LLM runtime.
The threat model: what are you actually protecting?
Before choosing controls, list the assets. A mature threat model includes more than vectors.
| Asset | What can go wrong | Typical control or test |
|---|---|---|
| Source documents | Unauthorized retrieval, stale permissions, accidental exposure | Preserve source ACLs; run cross-tenant negative tests |
| Embeddings | Disclosure, inversion attempts, poisoning, unauthorized export | Minimize exposure; restrict export and query access |
| Metadata | Tenant IDs, group names, PII, source URLs, classification labels | Minimize fields; avoid trusting user-supplied filters |
| Credentials | API-key theft, excessive scope, long-lived tokens | Separate identities; rotate, revoke, and inspect use |
| Indexes and collections | Unauthorized write, delete, or poisoning | Least privilege; separate ingestion and query identities |
| Backups and snapshots | Data leakage outside the primary database | Encrypt, restrict, restore-test, and define retention |
| Logs and traces | Prompts, retrieved chunks, identifiers, secrets | Centralize carefully; restrict and minimize retention |
| Control plane | Role changes, endpoint changes, key creation, deletion | Audit management actions and alert on sensitive events |
| Availability and integrity | Destructive deletes, denial of service, corrupted indexes | Recovery tests, deletion controls, patching, change review |
A useful way to review the architecture is to ask five questions at every boundary:
- Who is calling?
- What exact operation is allowed?
- Which tenant, collection, namespace, or rows are in scope?
- What evidence proves the decision?
- What happens after rotation, revocation, deletion, restore, or failure?
The most dangerous confusion: authentication versus authorization
Authentication answers: “Who are you?”
Authorization answers: “What may you do?”
Retrieval authorization adds a third question: “Which data may this identity see in this specific request?”
A service can have a valid Pinecone key, a valid Qdrant JWT, a valid Weaviate OIDC token, or a valid PostgreSQL role and still retrieve an unauthorized document if the application does not bind the caller’s identity to a trusted policy decision.
Do not let the user submit an arbitrary tenant_id and then treat that value as proof of tenancy. The tenant context should come from a verified identity or policy service, be bound to the request server-side, and be tested against tampering.
For relationship-heavy permissions, a policy service or ReBAC model may be more appropriate than trying to encode every rule inside a vector filter. Google Zanzibar’s relationship-based authorization model is a useful conceptual reference when access depends on users, groups, folders, projects, and inherited relationships rather than a single tenant column.
If your access model is genuinely relationship-shaped and you’re choosing an engine for your vector store’s permission layer, OpenFGA vs SpiceDB vs Zanzibar for vector-store authorization walks through the RAG-specific tradeoffs: pre-filtering cost, reverse-lookup cardinality, and revocation freshness.
A document can be the most relevant result and still be forbidden. Apply authorization before or during retrieval, not after the application has already collected sensitive chunks.
The comparison that matters: who owns each control?
Feature checklists hide operational responsibility. This matrix is more useful because it shows where the security work lives.
| Security domain | Pinecone | Qdrant | Weaviate | pgvector/PostgreSQL |
|---|---|---|---|---|
| Operating model | Managed service; BYOC changes data-plane responsibility | Cloud, hybrid, or self-hosted OSS | Cloud or self-managed Docker/Kubernetes | Extension inside PostgreSQL |
| Authentication | API keys, users, service accounts, SSO options | API keys and JWT patterns; self-hosted setup required | API keys, OIDC, configurable anonymous access | PostgreSQL roles and provider authentication |
| Network boundary | Private Endpoints for documented data-plane traffic | Operator must bind and isolate REST, gRPC, and peer paths | Operator must protect REST, gRPC, profiler, and cluster paths | Firewall, private networking, listen_addresses, and HBA |
| Tenant isolation | Namespaces and metadata patterns; application binding remains critical | Collection permissions plus application ACLs | Tenant/collection permissions plus application ACLs | Schemas, tables, roles, and optional RLS |
| Audit reality | Plan-gated management/control-plane logs; documented batch delivery | Audit logging requires configuration and central collection | RBAC authorization and role events; retention is your responsibility | Database, provider, and application logging must be designed together |
| Main security burden | Plan boundaries and application-level authorization | Perimeter, TLS, peer isolation, containers, and patching | Configuration, version drift, TLS, RBAC, and backups | Correct SQL security, RLS context, privileged paths, and lifecycle control |
Official documentation should be the final authority for current plan, version, region, and deployment claims. The Pinecone production security overview, Qdrant security documentation, Weaviate authentication and authorization documentation, and PostgreSQL row-security documentation describe the product-specific boundaries summarized above.
The right question is not “Which database has the most security features?” It is “Which team must configure, test, monitor, and recover each control?”
Decision matrix: choose by security workload, not feature count
Use this matrix as a starting point, not as a universal ranking. The right choice depends on your team’s ability to operate infrastructure and prove tenant-level authorization.
| If your priority is… | Start by evaluating… | The security trade-off | Decision test |
|---|---|---|---|
| Lower infrastructure operations | Managed Pinecone or managed product tiers | Less host hardening, but plan, control-plane, key, and application-ACL boundaries remain | Can you document exactly what the vendor logs, isolates, and does not enforce? |
| Maximum network and runtime control | Qdrant or Weaviate self-hosted | Your team owns exposure, TLS, containers, upgrades, logs, backups, and incident response | Can you patch, isolate, monitor, and restore the cluster under pressure? |
| Existing PostgreSQL governance | pgvector inside a well-operated PostgreSQL environment | Strong database primitives, but RLS, roles, pools, backups, and privileged paths become your design burden | Can you prove the application never uses an owner, superuser, or bypass-capable role? |
| Fastest path to a controlled pilot | Any option with a narrow, non-sensitive dataset | A pilot can hide production issues in tenant isolation, deletion, logging, and recovery | Have you defined the production security gates before expanding the dataset? |
The decision should be revisited when the data classification, tenant model, cloud boundary, or operational team changes. A product that is appropriate for a single-tenant internal search tool may be a poor fit for a multi-tenant customer-facing RAG service.
A universal hardening baseline
The implementation details differ, but the baseline is consistent.
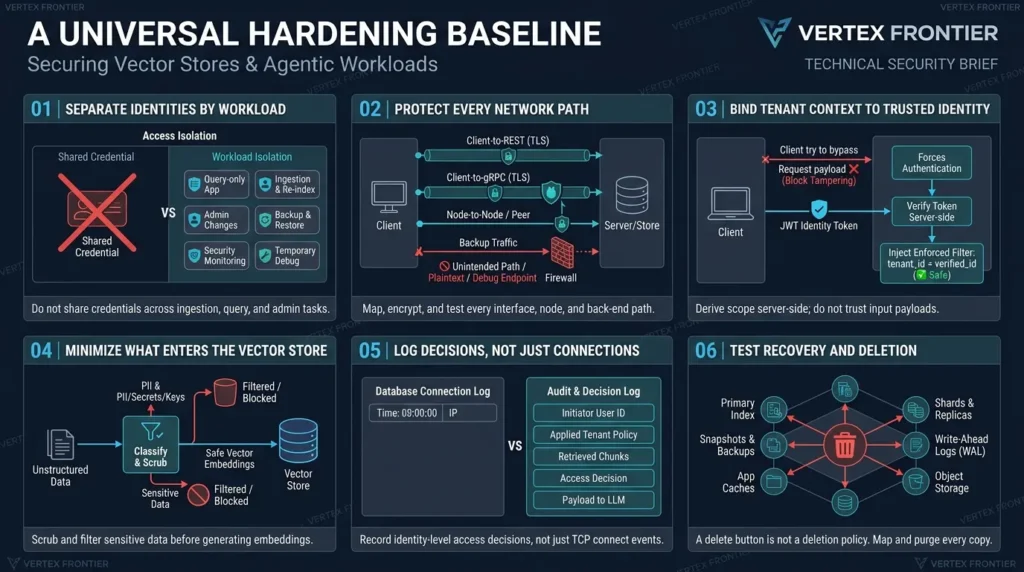
1. Separate identities by workload
Do not use one powerful credential for ingestion, retrieval, administration, backups, and CI/CD.
Create distinct identities for:
- Query-only applications
- Ingestion and re-indexing jobs
- Administrative changes
- Backup and restore operations
- Security monitoring
- Temporary migration or debugging work
A query service should not be able to delete collections. An ingestion worker should not be able to change organization-level settings. A backup identity should not become the default application credential.
This is also an identity-lifecycle problem. Service accounts and machine credentials need ownership, rotation, revocation, and evidence. Our guide to securing non-human identities in agentic AI is directly relevant when agents, scheduled jobs, and tool calls access the vector store.
2. Protect every network path
“TLS is enabled” is incomplete unless you list the paths it covers.
Review separately:
- Client-to-REST traffic
- Client-to-gRPC traffic
- Node-to-node or peer traffic
- Control-plane API calls
- Backup and object-storage traffic
- Administrative access
- Monitoring and profiler endpoints
Then test the negative case: can a client connect through an unintended port, plaintext listener, public interface, forwarded header, or debug endpoint?
3. Bind tenant context to trusted identity
The application should derive tenant scope from a verified identity or policy decision. It should not trust a tenant identifier supplied in the search body.
At minimum, test:
- A user changing the tenant ID
- A user removing the tenant filter
- A malformed filter that triggers a broader query
- A revoked user using a cached token
- A document whose ACL changed after indexing
- A deleted document still present in a replica or backup
To prevent parameter tampering, the application layer must construct the metadata filter exclusively from cryptographically verified claims rather than untrusted client payloads:
Python:
import os
from fastapi import FastAPI, Depends, HTTPException
from pinecone import Pinecone

app = FastAPI()
pc = Pinecone(api_key=os.environ["PINECONE_READONLY_KEY"])
index = pc.Index("enterprise-kb")

@app.post("/api/v1/search")
async def secure_rag_search(
    query_text: str,
    # Extract identity strictly from a verified, signed JWT token
    user_claims: dict = Depends(verify_jwt_token)
):
    # ❌ Vulnerability: Never accept a tenant identifier directly from the client request body
    # tenant_id = request.json.get("tenant_id")

    # ✅ Safe enforcement: Bind tenant scope server-side from verified token claims
    trusted_tenant_id = user_claims["tenant_id"]
    authorized_groups = user_claims.get("groups", [])

    # Construct an immutable query predicate that the client cannot override
    enforced_filter = {
        "$and": [
            {"tenant_id": {"$eq": trusted_tenant_id}},
            {"access_group": {"$in": authorized_groups}}
        ]
    }

    query_embedding = generate_embedding(query_text)

    # Execute search with guaranteed server-side boundary
    results = index.query(
        vector=query_embedding,
        top_k=5,
        include_metadata=True,
        filter=enforced_filter  # Mandatory filter injected at the application boundary
    )
    return results
This pattern guarantees that even if a caller attempts to tamper with the search payload, the retrieval engine restricts candidates strictly to the verified tenant scope.
4. Minimize what enters the vector store
Do not embed sensitive fields just because the model can process them.
Before ingestion, classify:
- Direct identifiers
- Secrets and credentials
- Financial or health data
- Internal URLs and file paths
- Access-control metadata
- Source-system version and deletion markers
Advanced RAG data preprocessing is the natural companion to this stage. Security begins before the first vector is written.
5. Design logging for decisions, not just connections
A database connection log may tell you that a query occurred. It may not tell you:
- Which user initiated it
- Which tenant policy was applied
- Which documents were returned
- Which ACL decision allowed each chunk
- Whether the result was passed to an LLM
Keep database audit events and application retrieval-decision events distinct. Both may be necessary.
6. Test recovery and deletion
A delete button is not a deletion policy.
Map every copy of the data:
- Primary index or table
- Replicas and shards
- Snapshots and backups
- WAL or change streams
- Object-storage exports
- Application caches
- Logs and traces
- Evaluation datasets
- LLM observability platforms
Then define what “deleted” means for each layer, how long it takes, and who can verify it.
Pinecone security: managed does not mean boundary-free
Pinecone removes much of the infrastructure management burden, but it does not remove the need to understand boundaries.
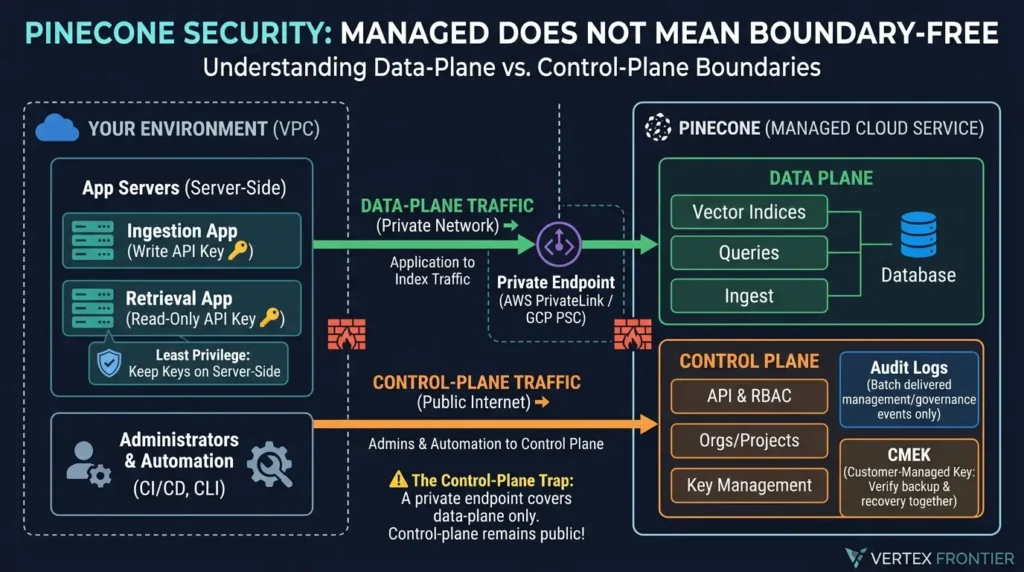
Identity and least privilege
Pinecone documents users, service accounts, and API keys as principals in its organization and project model. Its API-key and RBAC documentation describes role-based permissions and restrictions on which high-level project roles API keys can receive.
The practical baseline is straightforward:
- Keep keys on the server side.
- Use separate keys for ingestion and retrieval.
- Give query callers the narrowest documented role.
- Avoid placing long-lived keys in front-end code, notebooks, tickets, or CI logs.
- Rotate after staff changes, repository exposure, suspicious use, or incident response.
- Record which service owns each key.
Private Endpoints: the control-plane trap
Pinecone’s Private Endpoint documentation makes an important distinction: PrivateLink-style connectivity is for documented data-plane traffic, while control-plane access remains over the public internet.
That means a private endpoint does not automatically create a completely private Pinecone environment. Your architecture review should separately document:
- Data-plane DNS and routing
- Control-plane API access
- Administrator access
- Key and role management
- Endpoint creation and changes
- Audit-log delivery
- Cloud egress policies
This is a good example of why “private” is too vague a security claim.
Draw two separate arrows: application to index traffic, and administrators or automation to the Pinecone control plane. If your diagram has only one “private Pinecone” box, the boundary is probably underspecified.
CMEK and the recovery trade-off
Customer-managed encryption keys can improve key ownership and revocation control. They can also change recovery assumptions.
The current Pinecone CMEK guide describes project-scoped key behavior and reports a backup limitation for CMEK-enabled projects. Because this is a high-impact, plan- and product-sensitive claim, verify it against the current documentation before publication or implementation.
The larger lesson is stable even if the product detail changes: key custody, revocation, backup availability, and recovery testing must be reviewed together. Turning on customer-managed keys without running a restore test is not a complete security improvement.
Audit logs are evidence, not omniscience
Pinecone’s audit-log documentation describes plan-gated logs delivered to customer-controlled storage in batches. The supplied documentation describes management and control-plane events rather than a complete real-time record of every query and retrieved document.
Use those logs for what they actually prove: key, role, project, index, and governance activity within the documented scope. Add application-level retrieval logs if you need to answer, “Which user received which document, under which policy?”
Pinecone security example: a documented boundary, not a marketing claim
Challenge: A team needs private connectivity for sensitive index traffic.
Decision: Configure a Pinecone Private Endpoint and separately control management-plane access.
Outcome: The documented data-plane path can avoid the public internet, but the control plane remains a separate review item.
Lesson: A network feature must be evaluated by traffic type, not by its product label.
This is a documented product behavior example, not a claim of a customer incident or measurable business outcome.
Qdrant security: harden the perimeter before the application
Qdrant is where deployment mode changes the security conversation most sharply.
The official Qdrant security documentation states that self-hosted open-source deployments are not secure by default. The documented concerns include broad network binding, no authentication, and no TLS unless the operator configures them.
That should change the order of work. Do not begin with application filters. Begin with exposure.
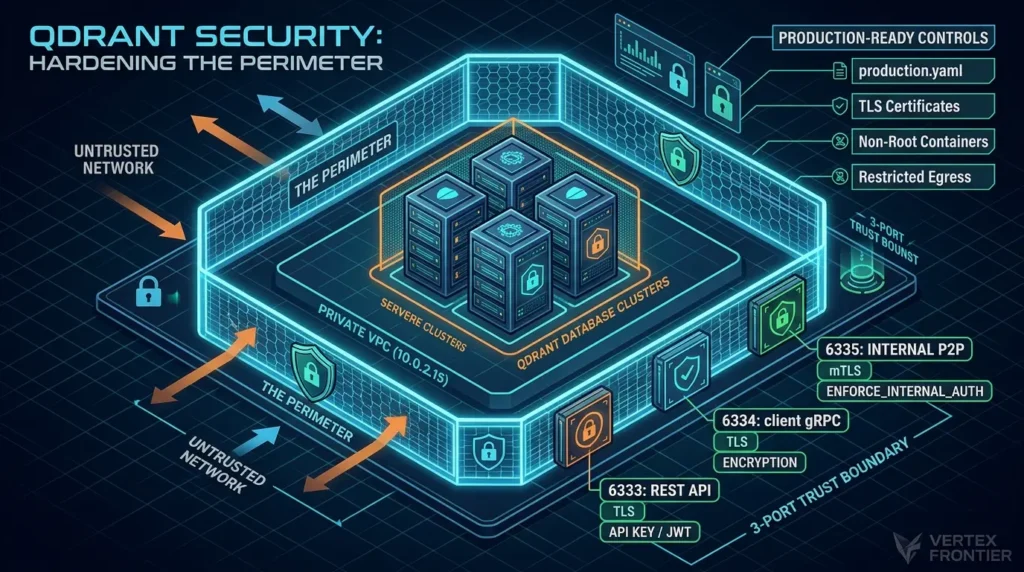
Qdrant’s three-port trust boundary
A self-hosted deployment commonly involves:
- 6333: REST API
- 6334: client gRPC
- 6335: internal peer-to-peer traffic
Protecting 6333 while leaving 6335 reachable from an untrusted network is not a complete deployment. The secure Qdrant tutorial and configuration documentation should be checked against the exact release and deployment method.
For distributed systems, internal authentication is a separate control from network isolation. The supplied research identifies version-sensitive enforce_internal_auth behavior and rollout requirements. Upgrade all peers, coordinate the shared secret, and test mixed-version failure before enabling it in production.
A production-ready production.yaml isolates cluster interfaces, enforces TLS on all listeners, and requires internal authentication across the peer port:
YAML:
# /qdrant/config/production.yaml
service:
  # Bind exclusively to private VPC interfaces rather than 0.0.0.0
  host: "10.0.2.15"       # Internal interface IP
  http_port: 6333
  grpc_port: 6334

  # Enforce client authentication and transport encryption
  api_key: "${QDRANT_API_KEY}"
  enable_tls: true

cluster:
  p2p:
    port: 6335            # Internal gossip / consensus port
    enable_tls: true      # Mutual TLS between cluster nodes

# Lock down peer synchronization with a dedicated shared secret
enforce_internal_auth: true
internal_api_key: "${QDRANT_INTERNAL_SECRET}"

tls:
  cert: "/etc/qdrant/tls/cert.pem"
  key: "/etc/qdrant/tls/key.pem"
  ca_cert: "/etc/qdrant/tls/ca.pem"
Notice that port 6335 is protected by enforce_internal_auth alongside transport encryption, blocking unauthenticated cluster node joins.
API keys, JWTs, and least privilege
Qdrant documents admin keys, read-only keys, and more granular collection-scoped access patterns. Use the least powerful credential that satisfies the operation.
A retrieval service should not use an admin key. An ingestion worker should not automatically receive delete permission. A key that can access one collection should not silently expand to every collection because of a missing or misread claim.
JWT access semantics are version-sensitive. Test both positive and negative cases, including an omitted access rule, an invalid collection name, a write attempted with a read-only identity, and a snapshot operation performed by a query identity.
Containers, egress, and snapshot recovery
Qdrant’s production guidance includes controls such as non-root execution, read-only root filesystems, reduced capabilities, and restricted egress.
Egress deserves special attention. Snapshot recovery and URL-based operations can turn a vector database into an unexpected network client. Restrict where the process can connect, and make object-storage access explicit rather than allowing arbitrary destinations.
Qdrant security example: an advisory changes the checklist
The Qdrant research package identified a GitHub security advisory concerning an arbitrary-file-write issue through the /logger surface in affected versions, with fixed-version details that must be rechecked against the canonical advisory and current release notes before publication.
Challenge: A version appears to work in functional testing.
Decision: Treat security advisories and release boundaries as part of deployment acceptance, not as optional maintenance.
Outcome: The precise affected and fixed versions determine whether the image can be approved; functional health alone cannot answer that.
Lesson: “The API responds” is not a security review.
Use the Qdrant GitHub security advisories and current release notes rather than relying on a third-party summary.
If you cannot show which interfaces, ports, credentials, TLS paths, peer connections, and egress destinations are exposed, the deployment is not ready for an untrusted network.
Weaviate security: configuration and version drift are the real risks
Weaviate offers API-key authentication, OIDC, and authorization controls, but the security result depends heavily on configuration precedence and release behavior.
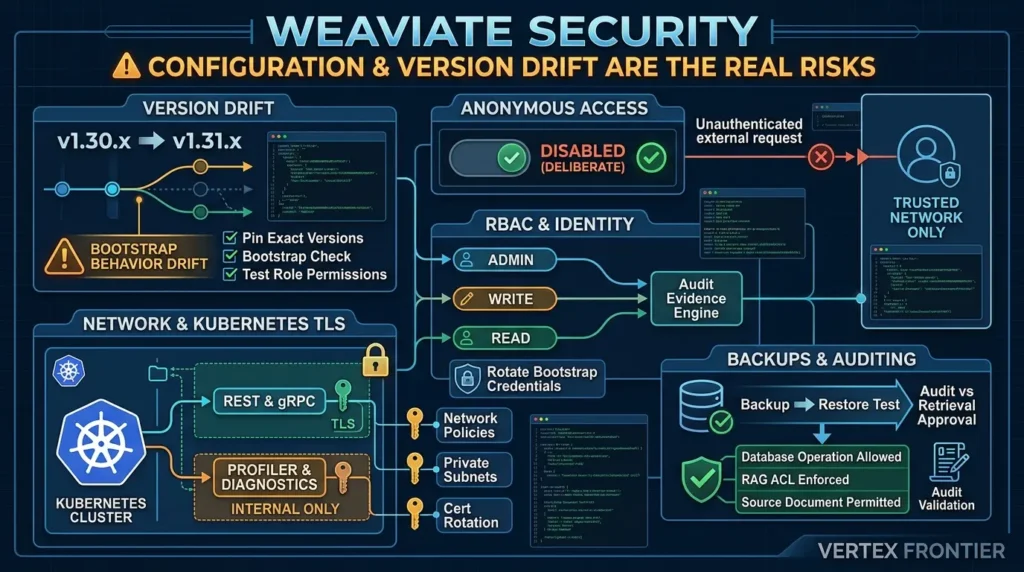
Disable anonymous access deliberately
The Weaviate authentication documentation describes configurable anonymous access and shows production-oriented configurations that disable it. Treat anonymous access as a setting to verify, not an assumption to inherit.
After deployment, test an unauthenticated request from outside the trusted network. A configuration file that looks correct is not proof that the running container, Helm chart, environment variables, and Cloud mode have the same effective behavior.
RBAC and bootstrap behavior
Weaviate’s RBAC documentation describes predefined and custom roles, including full-access and read-only patterns. The research also identified version-sensitive root-user bootstrap behavior around v1.30.x and v1.31.x.
The safe workflow is:
- Pin the exact image or chart version.
- Confirm how the first administrative identity is created.
- Create separate read, write, and administrative roles.
- Test role-management permissions independently from data permissions.
- Verify denied requests produce the expected audit evidence.
- Rotate or revoke the original bootstrap credential.
Do not assume that documentation for one minor release describes another release’s bootstrap behavior.
TLS means more than the REST endpoint
Self-managed Weaviate deployments may expose REST and gRPC paths, and operational endpoints such as a profiler may exist separately. Protect the client paths you use, keep profiler and diagnostics internal, and validate certificate rotation.
On Kubernetes, combine TLS with private subnets or network policies, restricted pod security, non-root containers, least-privilege service accounts, and encrypted storage. A secure application connection cannot compensate for a publicly exposed diagnostic endpoint.
Backups and module configuration
Backup credentials, object-storage IAM, KMS behavior, TLS parsing, and tenant state need an explicit restore test. A backup that completes successfully may still omit a tenant state you expected to recover.
Weaviate has also published security material concerning module or outbound configuration. Treat endpoint validation and credential exposure as part of the patching and configuration review, especially when a module can contact an attacker-influenced URL.
Use the Weaviate security and release material as a starting point, then verify affected versions and fixed releases against current vendor advisories and release tags.
Weaviate security example: audit approval versus retrieval approval
Challenge: An RBAC event shows that a user was allowed to query a collection.
Decision: Record a separate application-level authorization decision for the documents returned to that user.
Outcome: The audit trail can distinguish “database operation allowed” from “source document permitted.”
Lesson: A successful RBAC decision is not proof that a RAG ACL was enforced correctly.
pgvector security: PostgreSQL is the security model
pgvector is powerful partly because it lives inside PostgreSQL. That is also why it is easy to misunderstand.
The pgvector repository provides vector types and similarity indexes. It does not replace PostgreSQL authentication, authorization, TLS, logging, backup, or role management.
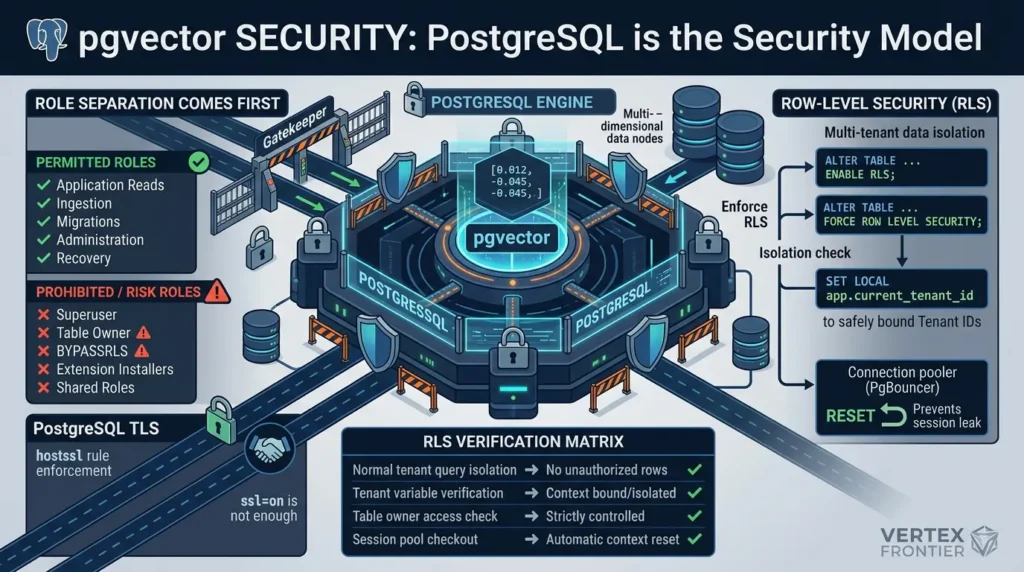
Role separation comes first
Do not let the application connect as:
- A superuser
- A table owner when RLS is expected to constrain access
- A role with
BYPASSRLS - A role that can install arbitrary extensions
- A shared role used by ingestion, querying, migrations, and backups
Create separate roles for application reads, ingestion, migrations, administration, and recovery. Keep extension installation and schema changes outside normal application permissions.
RLS is useful, but it has bypass paths
PostgreSQL’s row-level security documentation explains that RLS policies can restrict rows by user or session context. It also documents important exceptions: table owners typically bypass RLS, superusers and BYPASSRLS roles bypass it, and FORCE ROW LEVEL SECURITY changes owner behavior.
Other details matter too:
- With RLS enabled and no applicable policy, normal access is restricted.
TRUNCATEandREFERENCESare not governed by row policies in the same way as row reads and writes.SECURITY DEFINERfunctions can change the privilege context.- Cross-table policy checks can introduce race and information-leak concerns.
- Connection pools can leak session context if tenant variables are not reset.
A similarity query must include the authorization predicate in the database operation or in a trusted retrieval layer. Filtering results after the query is dangerous because unauthorized rows may already have entered memory, logs, metrics, or an LLM prompt.
The following configuration demonstrates how to lock down table owners with FORCE ROW LEVEL SECURITY and bind tenant scope safely using transaction-scoped session variables:
SQL:
-- 1. Enable RLS and explicitly prevent table owners from bypassing policies
ALTER TABLE document_embeddings ENABLE ROW LEVEL SECURITY;
ALTER TABLE document_embeddings FORCE ROW LEVEL SECURITY;

-- 2. Restrict row reads to a cryptographically validated session setting
CREATE POLICY tenant_isolation_policy ON document_embeddings
    FOR ALL
    TO application_role
    USING (tenant_id = NULLIF(current_setting('app.current_tenant_id', true), '')::uuid);

-- 3. Execution pattern: enforce tenant context before running the vector search
BEGIN;
  -- Set by the trusted application tier (never from raw client input)
  SET LOCAL app.current_tenant_id = 'a1b2c3d4-e5f6-7a8b-9c0d-1e2f3a4b5c6d';

  SELECT id, content, 1 - (embedding <=> '[0.012, -0.045, ...]'::vector) AS similarity
  FROM document_embeddings
  ORDER BY embedding <=> '[0.012, -0.045, ...]'::vector
  LIMIT 5;
COMMIT;
-- Note for connection poolers (e.g., PgBouncer): SET LOCAL guarantees
-- the setting is discarded immediately at transaction boundary, preventing context leakage.
Using SET LOCAL within a transaction boundary ensures the session variable is automatically cleaned up when the connection returns to a pooler like PgBouncer, eliminating cross-tenant session bleed.
PostgreSQL TLS: ssl=on is not enough
PostgreSQL’s SSL/TLS documentation and pg_hba.conf documentation should be read together.
The practical point is simple: enabling SSL support does not automatically force every client to use an encrypted connection. pg_hba.conf rules are evaluated in order, and the first matching rule is used. Use deliberate hostssl rules, certificate verification where appropriate, private network controls, and tests that prove plaintext connections fail.
A safe RLS verification matrix
Before trusting pgvector for tenant isolation, test more than one successful query.
| Test | Expected result | Why it matters |
|---|---|---|
| Normal tenant role queries another tenant | No rows or only authorized rows | Baseline isolation |
| Application changes a tenant session variable | Request is rejected or policy remains bound to trusted context | Prevents caller-controlled scope |
| Table owner runs the same query | Behavior is explicitly understood and controlled | Owners may bypass RLS |
Superuser or BYPASSRLS path | Never used by the application | RLS cannot compensate for an overpowered role |
| Pool checkout after another tenant request | Tenant context is reset | Prevents session contamination |
| Restore, replica, export, and admin job | Scope and access are documented and tested | Primary-table RLS does not secure every copy |
pgvector security example: mature database, shifted responsibility
Challenge: A team wants vector search without adding a separate managed database.
Decision: Use PostgreSQL roles, RLS, TLS, and operational controls around pgvector.
Outcome: The team gains PostgreSQL’s mature security primitives, but must implement and test tenant context, privileged paths, backups, and extension patching.
Lesson: “It runs inside PostgreSQL” can reduce infrastructure sprawl; it does not make an unsafe role design safe.
The extension’s release history and changelog should be part of the patch process. Do not convert a changelog entry into a CVE claim without verifying the underlying issue, affected versions, and exploitability.
Multi-tenancy: namespaces, collections, shards, and rows are not equal
Different products use different isolation primitives:
- Pinecone namespaces
- Qdrant collections and collection-scoped keys
- Weaviate tenants and collections
- PostgreSQL schemas, tables, tenant columns, and RLS
These primitives differ in operational behavior, permission scope, deletion semantics, and failure modes. They should not be treated as interchangeable labels for “tenant isolation.”
A defensible multi-tenant design has four layers:
- Identity: the caller is authenticated.
- Policy: the caller’s access is evaluated against current source permissions.
- Storage scope: the query is constrained to the permitted namespace, collection, tenant, or rows.
- Negative evidence: tests prove that tampering, stale metadata, revocation, and deletion fail closed.
The fourth layer is the one most designs skip.
A metadata filter is not a policy engine. It is an input to a query. Treat it as untrusted until the application creates it from a verified authorization decision.
Audit logs, backups, and deletion: the neglected security surface
Audit logs have different meanings
| Product | What the documentation indicates | What it does not automatically prove |
|---|---|---|
| Pinecone | Plan-gated management/control-plane events with documented batch delivery | Complete real-time query, prompt, or retrieved-document history |
| Qdrant | Configurable audit logging with local storage and rotation considerations | Durable centralized evidence unless you ship and protect the logs |
| Weaviate | RBAC authorization and role-management events | Correct source ACL decisions or long-term tamper-resistant retention |
| PostgreSQL/pgvector | Database, provider, and application logging options | A complete record unless query identity, tenant, result, and policy decision are designed into the application |
Design the audit event you actually need. For a sensitive retrieval, that may include request ID, user identity, tenant, policy version, query service identity, selected data scope, decision, and downstream destination. Avoid logging raw sensitive content by default.
Backups are part of the threat model
Backups can outlive a user’s access and can be restored into a less protected environment. Review:
- Who can create and restore them
- Whether they include inactive or offloaded tenants
- Which keys protect them
- Whether restore changes access semantics
- Whether snapshots can be fetched from arbitrary URLs
- How long deletion takes to reach backup media
- Whether logs and exports retain sensitive metadata
Pinecone’s CMEK/recovery trade-off, Qdrant snapshot and egress concerns, Weaviate tenant/backup behavior, and PostgreSQL WAL and replica paths all demonstrate the same principle: primary-storage security is only one part of lifecycle security.
For broader recovery architecture, the enterprise ransomware protection strategy provides relevant context on detection and recovery controls, even though it is not a vector-database guide.
Deletion must be demonstrated
A deletion test should answer:
- Is the vector gone from the primary store?
- Is the source document gone from replicas?
- Can an old snapshot restore it?
- Does a WAL or export retain it?
- Does the cache return it?
- Does an evaluation or tracing platform retain it?
- Does the application reject the old document after ACL revocation?
If the answer is unknown, describe deletion as incomplete rather than guaranteed.
Before and after: a realistic hardening transformation
Before
- One shared admin credential is used by the API, ingestion job, notebook, and CI pipeline.
- A tenant ID arrives from the browser and becomes a vector filter.
- Qdrant is reachable on a public interface.
- Weaviate anonymous access was never tested.
- PostgreSQL connects with a role that owns the vector table.
- Logs record HTTP status codes but not policy decisions.
- Backups are enabled but restore scope and deletion behavior are unknown.
After
- Query, ingestion, migration, backup, and security identities are separate.
- Tenant scope is derived from verified identity and policy, then bound server-side.
- REST, gRPC, and peer ports are isolated and tested independently.
- Anonymous requests fail, RBAC is pinned to a tested version, and secrets are outside committed configuration.
- PostgreSQL application roles cannot bypass RLS, and pool context is reset on every checkout.
- Retrieval decisions are logged with identifiers and policy versions without copying raw sensitive content.
- Restore and deletion tests cover primary storage, replicas, snapshots, exports, logs, caches, and traces.
The result is not “secure forever.” It is a system with measurable assumptions and failure tests.
A practical pre-production workflow
Use this sequence for a new deployment or a major migration.
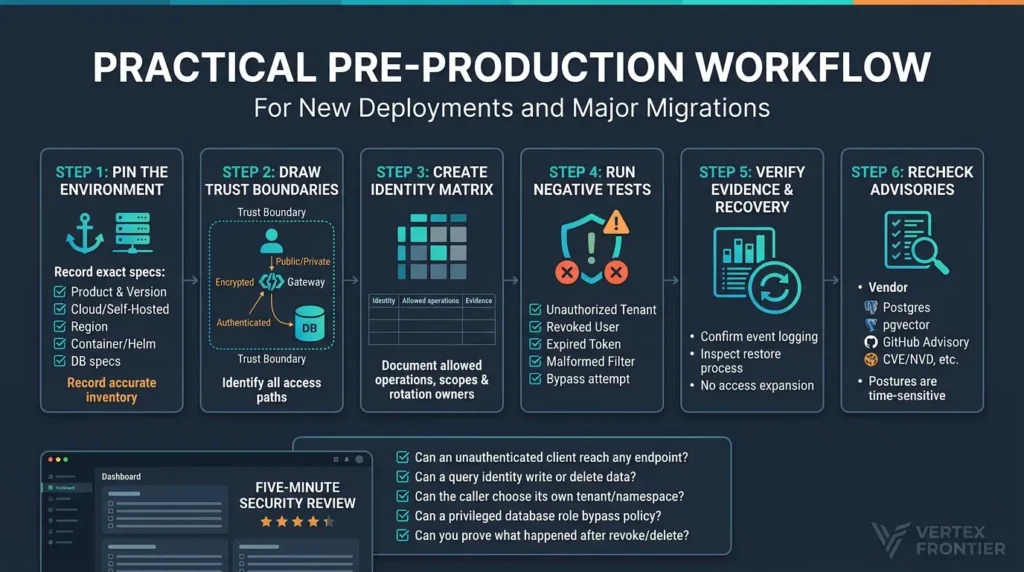
Step 1: Pin the environment
Record:
- Product and exact version
- Cloud or self-hosted mode
- Region and provider
- Container image or Helm chart
- PostgreSQL major/minor and pgvector version
- Authentication and authorization configuration
- Backup and logging destinations
Without this inventory, version-sensitive security claims are difficult to reproduce.
Step 2: Draw the trust boundaries
Include users, agents, API gateways, policy services, embedding workers, vector database endpoints, object storage, backups, logs, caches, and LLM providers.
Mark which path is public, private, encrypted, authenticated, and logged.
Step 3: Create the identity matrix
For every identity, record allowed operations, data scope, credential lifetime, rotation owner, and revocation procedure.
A simple matrix catches excessive permissions earlier than a generic RBAC review.
Use this template during design review. Replace the role names with the identities in your system and record the evidence location for each decision.
| Identity | Allowed operations | Data scope | Credential owner | Evidence to retain |
|---|---|---|---|---|
| Query service | Read/search only | Policy-approved tenant or collection scope | Application/platform team | Denied-write test and retrieval decision log |
| Ingestion worker | Insert/update; narrowly scoped delete if required | Assigned source and tenant scope | Data/platform team | Write scope, source lineage, and revocation test |
| Migration/admin | Schema, index, collection, or project changes | Explicit maintenance window | Platform/security team | Change record and audit event |
| Backup/restore | Create, restore, and validate backups | Recovery environment only unless approved | SRE/platform team | Restore scope, key usage, and post-restore ACL test |
| Security monitoring | Read logs and investigate events | No vector writes by default | Security operations | Alert, retention, and tamper-protection record |
Step 4: Run negative tests
Do not test only “authorized user gets the right result.” Test:
- Unauthorized tenant
- Revoked user
- Expired token
- Missing ACL metadata
- Malformed filter
- Read-only identity attempting writes
- Public port exposure
- Anonymous request
- Owner or bypass role
- Restored backup in a different environment
Step 5: Verify evidence and recovery
Confirm that security events arrive where expected, that operators can investigate them, and that the restore process does not silently expand access.
Step 6: Recheck advisories and vendor documentation
Security posture is time-sensitive. Re-open the official Pinecone, Qdrant, Weaviate, PostgreSQL, pgvector, GitHub Advisory, and NVD pages before publication or production approval.
Five-minute security review
- Can an unauthenticated client reach any vector endpoint?
- Can a query identity write, delete, or administer data?
- Can the caller choose its own tenant or namespace?
- Can a privileged database role bypass the intended policy?
- Can you prove what happened after a revoke, restore, or delete?
Vector database production-readiness checklist
Use this checklist as a release gate, not as a compliance certification. A checked box means the team has evidence for the control in the exact environment under review.
| Domain | Release-gate question | Evidence to attach | Status |
|---|---|---|---|
| Identity | Are query, ingestion, admin, backup, and monitoring identities separate? | Role matrix, key inventory, rotation owner | ☐ Pass ☐ Fail ☐ N/A |
| Network | Are every client, peer, admin, backup, and diagnostic path private or explicitly approved? | Port map, firewall rules, TLS test results | ☐ Pass ☐ Fail ☐ N/A |
| Authorization | Is tenant scope derived from a trusted identity rather than a user-controlled filter? | Policy flow, negative-test results, ACL freshness test | ☐ Pass ☐ Fail ☐ N/A |
| Secrets | Can leaked credentials be revoked, rotated, and traced to an owner? | Rotation record, revocation test, audit event | ☐ Pass ☐ Fail ☐ N/A |
| Logging | Can the team identify who queried what scope and which policy decision was applied? | Sample event, retention policy, alert route | ☐ Pass ☐ Fail ☐ N/A |
| Recovery | Has restore been tested without expanding tenant access or exposing old data? | Restore report, key mapping, post-restore ACL test | ☐ Pass ☐ Fail ☐ N/A |
| Deletion | Can the team explain where deleted vectors, metadata, logs, replicas, and exports remain? | Deletion test, retention map, exception list | ☐ Pass ☐ Fail ☐ N/A |
Do not approve the deployment because every row says “Pass” if the evidence is only a configuration screenshot. For high-risk systems, include a failed negative test, the remediation, and the retest result in the release record.
A practical vector-security readiness score
A score can help a team prioritize work, but it is not a certification and it cannot compensate for a failed critical control. Score each domain from 0 to 5:
| Score | Meaning | Evidence standard |
|---|---|---|
| 0 | Unknown or absent | No owner, configuration, or test |
| 1–2 | Partially defined | Some configuration exists, but scope or negative tests are missing |
| 3 | Controlled | Owner, configuration, and at least one verification test exist |
| 4 | Operationally evidenced | Positive and negative tests, monitoring, and review cadence exist |
| 5 | Continuously verified | Automated or recurring tests, alerting, ownership, and recovery evidence exist |
Score these domains: identity and key management, network exposure, tenant isolation, document-level authorization, logging and detection, backup and deletion, and patch/advisory management. A total score can highlight weak areas, but a single critical failure, such as public unauthenticated access or a query role that can delete data, should block release regardless of the total.
Leaked vector-database credential response playbook
If an API key, database password, JWT signing secret, cloud identity, or Kubernetes secret may have leaked, treat the event as active until the scope is known.
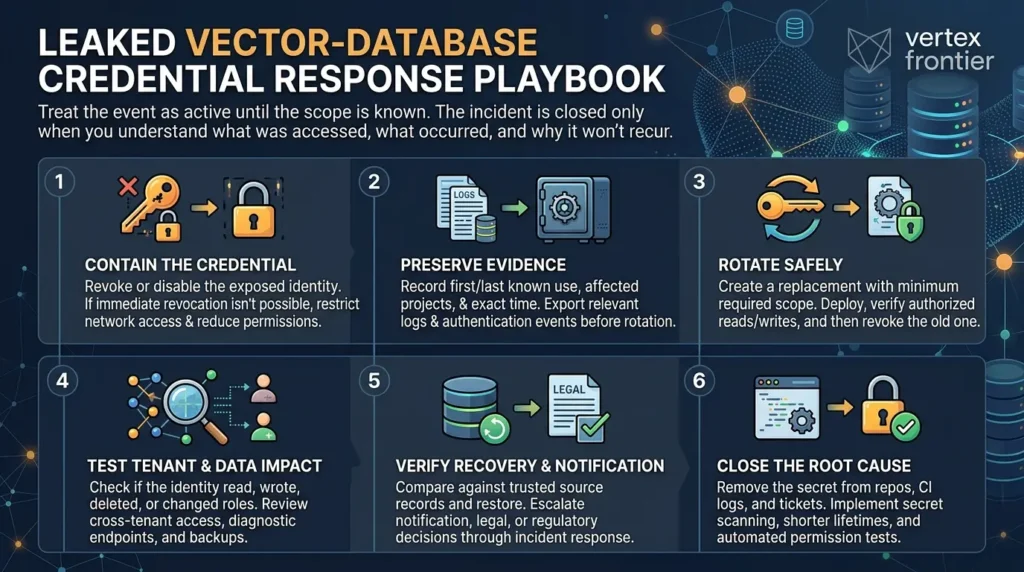
1. Contain the credential
Revoke or disable the exposed identity using the vendor or database control plane. If immediate revocation is not possible, restrict network access and reduce the identity’s permissions while preserving evidence.
2. Preserve investigation evidence
Record the credential owner, first and last known use, affected projects or collections, source repository or log, and the exact time window. Export the relevant management, authentication, query, and application-policy events before retention or rotation removes context.
3. Rotate safely
Create a replacement credential with the minimum required scope. Update the service through a controlled deployment, confirm successful authorized reads and writes, then revoke the old credential. Do not delete the old audit evidence just because the secret has been rotated.
4. Test tenant and data impact
Check whether the identity could read, write, delete, export, create keys, change roles, access snapshots, or reach peer and diagnostic endpoints. Review cross-tenant access, unexpected writes, deletion events, and changes to filters or namespaces.
5. Verify recovery and notification decisions
If data may have been altered or deleted, compare against trusted source records and restore points. Confirm that a restore does not recreate the same exposed credential or broaden access. Escalate notification, legal, contractual, or regulatory decisions through the organization’s incident-response process; this article does not determine those obligations.
6. Close the root cause
Remove the secret from repositories, notebooks, CI logs, images, and tickets where possible. Add secret scanning, shorter credential lifetimes, ownership metadata, and a test that fails when a query identity receives administrative permission.
The incident is not closed when the key is rotated. It is closed when the team can explain what the key could access, what it actually did, what data may have been affected, and why the same exposure should not recur.
Common mistakes to avoid
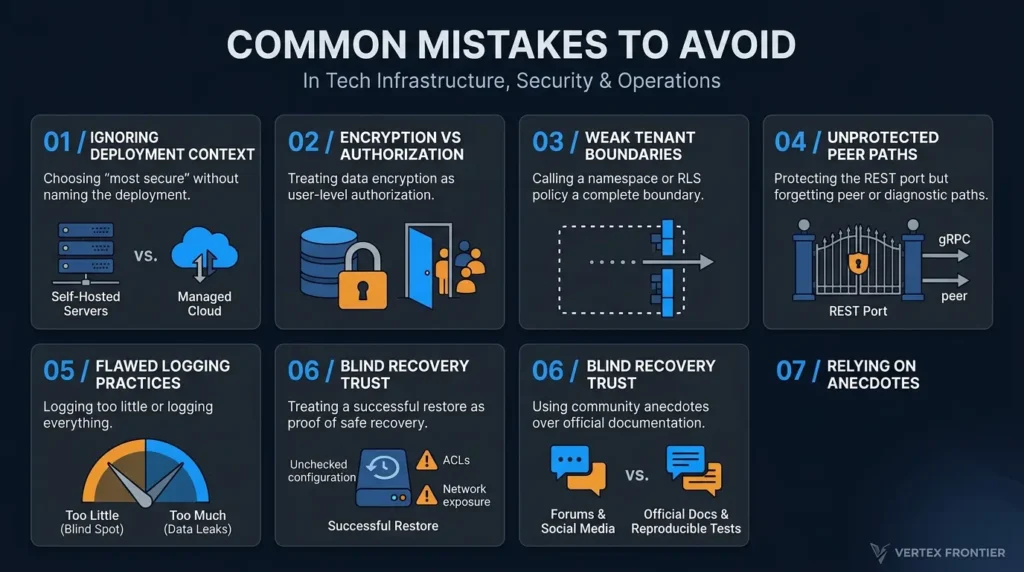
Mistake 1: Choosing the “most secure” product without naming the deployment
A managed service and a self-hosted cluster do not give the same team the same responsibilities. Compare control ownership and operational maturity, not marketing categories.
Mistake 2: Treating encryption as authorization
Encryption protects data in defined states and paths. It does not decide whether a user may retrieve a document.
Mistake 3: Calling a namespace or RLS policy a complete tenant boundary
Test privileged roles, connection pools, snapshots, exports, stale ACLs, and administrative paths. A boundary is a claim that needs evidence.
Mistake 4: Protecting the REST port and forgetting peer or diagnostic paths
Qdrant’s 6335 peer path and Weaviate’s gRPC and profiler paths demonstrate why endpoint inventories must be explicit.
Mistake 5: Logging too little or logging everything
Minimal logs make investigation impossible. Raw prompts and retrieved documents in every log stream create a second data-leak problem. Log decisions, identifiers, policy versions, and references selectively.
Mistake 6: Treating a successful restore as proof of safe recovery
Check tenant scope, credentials, encryption, source ACLs, network exposure, and post-restore monitoring.
Mistake 7: Using community anecdotes as universal evidence
Reddit and YouTube are valuable for discovering failure modes and practical questions. They are not substitutes for current product documentation, release notes, or reproducible tests.
Advanced insights for security teams
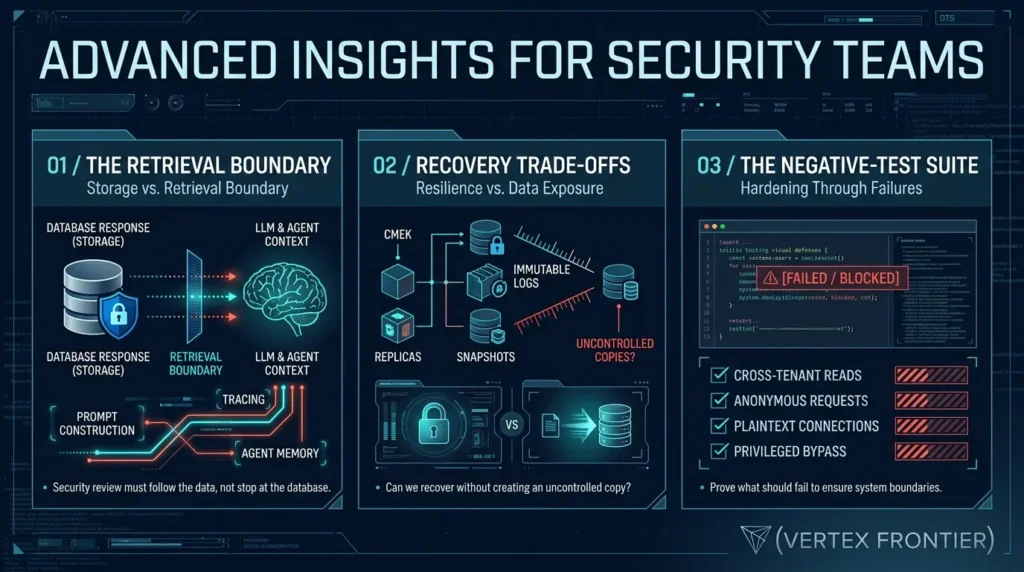
Insight 1: The retrieval boundary is more important than the storage boundary
A database can be well protected while the application still exposes too much context to an LLM. The security review should follow the data after retrieval, not stop at the database response.
That includes prompt construction, tool calls, agent memory, tracing, evaluation, caching, and human review. Agent memory architecture is relevant here because stored memory and retrieved context often have different authority, lifetime, and deletion requirements.
For the broader agent engineering concepts those pieces belong to, the 20-concept map that spans tool calls, memory, tracing, and evaluation, see our flagship overview.
Insight 2: Recovery controls can create security trade-offs
CMEK, immutable logs, long retention, replicas, and snapshots improve certain security or resilience properties while extending the number of places where sensitive data exists. The correct question is not “Do we have backups?” but “Can we recover without creating an uncontrolled copy?”
Insight 3: The best hardening checklist is a negative-test suite
A list of settings can be correct while the running system is not. A negative-test suite proves what should fail: cross-tenant reads, writes with read-only keys, anonymous requests, plaintext connections, stale ACLs, and privileged bypass paths.
Final verdict
Vector database security is not won by selecting the product with the longest feature list. It is won by making the trust boundaries explicit and testing the paths that should fail.
Choose Pinecone when managed infrastructure and enterprise controls fit your requirements, but separate data-plane privacy from control-plane access and verify plan-dependent features. Choose Qdrant self-hosting only when your team is prepared to harden the network, peer paths, containers, egress, credentials, logs, and patch cycle.
Treat Weaviate configuration and version behavior as first-class security concerns. Choose pgvector when PostgreSQL is the right operational foundation, and then design its roles, RLS, TLS, pooling, backups, and extension lifecycle with the same care you would give any security boundary.
The most important design decision is cross-product: never let database-level access stand in for document-level authorization.
If a user can change the tenant context, if a revoked document survives retrieval, if a privileged role bypasses the policy, or if a restore recreates access without review, the system is not hardened no matter how impressive the database’s security page looks.
FAQ: vector database security
Is a vector database secure if it uses API keys?
No. API keys provide an authentication and authorization mechanism, but security also depends on key scope, network exposure, TLS, tenant binding, source-document ACLs, logging, backups, and revocation testing.
Which is more secure: Pinecone, Qdrant, Weaviate, or pgvector?
There is no universal answer. Pinecone reduces infrastructure responsibility but has plan and control-plane boundaries. Qdrant and Weaviate self-hosting require careful perimeter, container, TLS, and version hardening. pgvector inherits PostgreSQL’s powerful controls but shifts more responsibility to SQL roles, RLS, pooling, backups, and patching.
Is Qdrant safe to expose to the public internet?
A self-hosted Qdrant deployment should not be treated as safe for public exposure by default. The official security guidance describes authentication, TLS, network binding, peer isolation, and audit logging as configuration work that must be completed before production use.
Does a Pinecone Private Endpoint make the whole service private?
No. Pinecone’s documentation distinguishes data-plane traffic from control-plane access. Private Endpoint coverage, DNS, region, project scope, and plan requirements should be verified for the exact deployment.
Can PostgreSQL RLS secure a pgvector multi-tenant table?
It can be part of a strong design, but it is not automatic. Test table owners, superusers, BYPASSRLS roles, FORCE ROW LEVEL SECURITY, SECURITY DEFINER functions, pool context, background jobs, backups, replicas, and operations not governed like normal row reads.
Should sensitive data be stored in embeddings?
Only after a data-classification and threat-model decision. Minimize sensitive metadata, restrict vector access and export, understand the model and retrieval exposure, and review backups, logs, caches, and downstream LLM traces. Do not assume an embedding is either harmless or directly reversible in every situation.
📋 Article Timeline & History
Successfully updated on October 13, 2026 with the latest details.
This article was originally published on October 7, 2026.

Was this article helpful?

[…] and source documents that ransomware can encrypt or wipe just like any other asset. Our guide to vector database backups, audit logs, and deletion covers recovery testing […]